
Products
Solutions
Resources


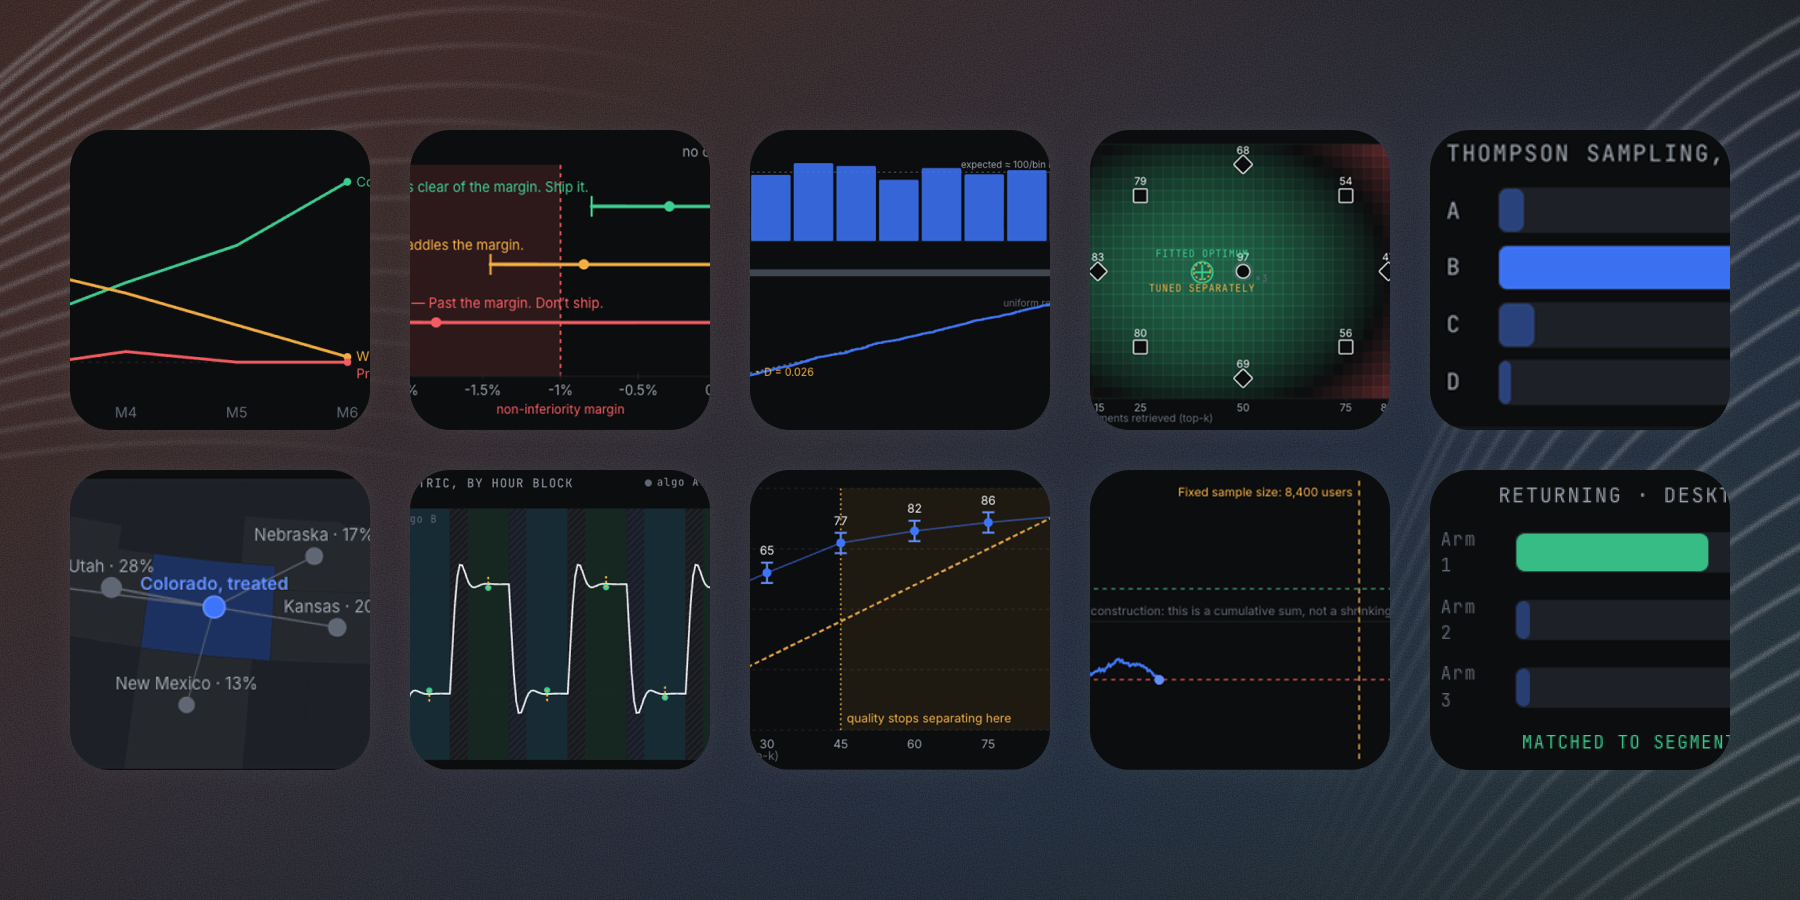
You have something on your roadmap right now like a new pricing model, a campaign, a product change, a growth loop. Someone is going to ask you to prove it worked. It could be your VP, your COO, or maybe you yourself asking the question. Whoever it is, they want to know whether the change actually caused the result, not just that something happened to move in the intended direction.
This is what separates a team that just runs tests from a team that actually knows what’s working. Most teams know only one test, the gold standard of measurement: the A/B test. It is the go-to measurement framework in online growth and product development. But A/B tests don’t work for a lot of situations, like small samples, network effects, high-risk downside protection, or questions that require a different kind of design entirely.
For each of those problems, someone has already researched and published an alternative experiment design. Some designs are popular, but many are not known outside data science circles. Product and business stakeholders may have a specific causal or incremental question that an A/B test cannot answer, but they don’t know if there are any other ways to answer it, unless they have a team of data scientists and economists who are well-versed in these methods.
Many companies cannot afford to have an in-house data science function. So they keep running simple A/B tests, without realizing the design pitfalls that can invalidate the results and assuming that they’re still running a rigorous experimentation program.
The goal of this post is to make you aware of several different experiment designs that go beyond simple A/B tests, and to teach you which to use when and what kinds of questions these designs can actually answer.
Want more experiment design? Watch the webinar covering these topics in detail, available on demand here.
Asking the right questions
Before we get into the methods, it helps to understand where A/B tests actually break.
Consider the Monte Carlo Casino in Monaco, the mecca of probability theory. In the 1880s, an engineer named Joseph Jagger figured out that one of the roulette wheels was behaving oddly. He identified a mechanical bias in how the wheel was landing, then exploited that bias systematically. He won an enormous amount of money in a single day, enough to break the casino’s bank. The casino realized the problem and had to immediately fix the wheel.

Fifty years later, in the same casino, a roulette wheel hit black twenty-six times in a row. This is after fixing the bias that existed half a century ago! The probability of that happening is about one in 137 million. Gamblers lost fortunes that day. When people saw black come up a few times in a row, they started betting more on red, convinced that red was imminently due. They formed a relationship between spins that didn’t actually exist. Each spin is independent of the prior spin. But when put into certain situations, humans start making logical connections that aren’t really there.
Now consider an example from Greek mythology, Pandora’s Box. Zeus gave Pandora a box and told her never to open it, knowing full well that her curiosity would win out. When she opened it, evil and disease spread everywhere. The point is that one person’s action (curiosity in this case) affected everyone else. In experiments, this happens all the time, especially in marketplaces where scarce resources are shared by all units. You test a new search ranking algorithm and see a lift, but did you consider scarce inventory availability shared by all the units across variants, or did you just move the demand around?
An experiment is a research question
Every research question involves an experiment design process, i.e., who are you studying, what outcomes you care about, what effect size would actually matter or change your decision. All of this gets defined before selecting the statistical inference method itself. Based on the limitations you encounter with those questions, you might have to pick the stats method precisely.
However, in the online experimentation field, the statistical inference method is already selected for you. Most commonly, it is either the frequentist z-test or Bayesian stats. And the unsuspecting experimenter ends up force-fitting the method to every question at hand, without realizing the pitfalls.
This is the first way experiments go wrong: violating the assumptions that make the measurement math/statistical method work. When you run an A/B test, you’re relying on four core assumptions:
Your samples have to be independent and identically distributed (I.I.D.). This is like how roulette spins are independent of prior spins and follow the same underlying distribution, even if the distribution is skewed like Joseph Jagger’s wheel.
No one person's experience should affect anyone else's (stable unit treatment value assumption, or SUTVA). This is like Pandora’s box.
You need to decide your sample size upfront (frequentist only).
The unit you randomize on has to match the unit you measure.
Violate any of these, and the standard t-test or z-test gives you a false answer without you suspecting it. When all four hold, you have a well-designed A/B test. But in practice, one of them often doesn’t hold.
There’s also a second, more subtle way experiments go wrong: you can violate no assumptions at all and still get an answer, but to the wrong question.
In Greek mythology, Odysseus had to navigate past the sirens on his way home from Troy. The conventional question was, “Can we survive the Siren’s song?” That’s a fair question. However, to Odysseus, that question didn’t matter anymore. The witch, Circe, had told him to put wax in his crew’s ears as they sailed past, and they’d survive just fine. So now, Odysseus wanted an answer to a different question: “What is the Siren’s song about?”

By being deliberate with his question, he designed a situation on the ship such that he could isolate the signal from the noise. He filled his crew’s ears with wax, but left his own open while tied to the mast, instructing his crew not to release him, no matter how much he begged. He was able to isolate the one thing he actually wanted to learn: What were they singing about?
By reframing the question, he was able to measure something precise instead of settling for a yes-or-no answer to the wrong problem. Many experiments fail in exactly this way. You run a clean test, get a clear answer, but you’ve answered the wrong question. This is called a Type III error, and even though it’s talked less about than breaking assumptions, it matters more.
You test whether a form with five fields beats a form with seven fields on conversion rate. It does, and you ship it, only to realize months later that the leads from the five-field form were all junk. They never engaged in follow-ups. You were asking the wrong question. The right question was which form produces more qualified leads, not just more leads.
Or you test a caching change to make product pages faster. You already know that caching works in making pages faster. So that’s not what you should ask in the experiment. The real question to ask is, "What might break that I haven’t thought of if I implement caching?” You might introduce user confusion or break another feature two pages down the funnel.
These are the two failure modes we need to fix: breaking the assumptions and asking the wrong question. These failures require different fixes. The first kind needs better statistical methods or better experiment design. The second kind needs better framing of the question.
Fixing the assumptions
When you violate statistical assumptions, the good news is that solutions already exist that fix the violations. They’re not new, but they’re also not always part of the experimentation platform you’re using.
Consider a search ranking experiment. You randomize at the user level and measure clicks per search. But one user’s searches aren’t independent of their prior searches. Remember the roulette wheel where twenty-six blacks came in a row? They were independent, but gamblers established relationships between the events. In the search case, two searches are NOT independent, but many people fail to see that connection. If the users didn’t find what they wanted, they’d refine their query. Your metric violates the independence assumption. The solution is the delta method, which adjusts for the covariance between clicks and searches so your confidence interval reflects your actual uncertainty.
Or take a B2B product feature test. You randomize at the user level, but users in the same account talk to each other. If an admin in that account adopts the feature, other users in the same account tend to follow. One person’s behavior affects everyone else’s. This violates SUTVA. The fix is cluster randomization. You randomize entire accounts instead of users, then measure at the user level but adjust for the fact that your real sample size is the number of clusters, not the number of users. You also apply the delta method to get your variance right.
The same principle applies to each broken assumption. There’s a statistical fix, but it requires knowing that your assumption is broken in the first place.
Fixing the question
The second kind of failure is harder to fix because there’s no single solution. It depends on what you’re actually trying to learn. Consider these four examples.

1. You’re testing a new payment processor and need to ensure it doesn’t make things worse. In this case, you don’t need a two-sided typical z-test to measure the A/B result. You need a slightly modified, one-sided non-inferiority test for the same A/B setup. You set a margin of acceptable decline and test whether the new processor stays above it. You’re not looking for a winner but rather proving parity exists.

2. You’ve shipped a bunch of improvements over a quarter, and leadership is asking whether the program is actually working; an individual A/B test won’t answer that. You need a holdout. Before you ship anything, set aside a small slice of users who never get any of your improvements. Measure the gap between them and everyone else after a quarter. That gap is the accumulated impact of everything shipped. This catches the winner’s curse, where a test shows a win that disappears once you ship it to everyone.

3. You’re running a brand campaign in a specific market and need to know the true lift, but you cannot randomize markets. You need a synthetic control, which is an artificial twin market out of similar untouched weighted markets, so it tracks your treated market before the campaign. After the campaign, any gap between reality and the synthetic twin is your incremental lift.

4. You’re testing a new matching algorithm in a rideshare marketplace. You can’t split riders into control and treatment because they share the same pool of resources, the drivers. A switchback test design cycles the entire marketplace between the old and new algorithm hour by hour, so you can measure the effect without splitting a shared system.
These are the design questions, not statistical questions. You ask them before you pick your statistical method. And the answer depends on what you’re actually trying to learn.
Methods worth a mention
There are a few more designs that deserve special mention, even if briefly. They solve specific problems that show up often enough to matter. All these are set up as a typical A/B/n test, but designing the variants smartly or choosing the correct decision framework can help answer different questions for different situations.
A/A test
An A/A test runs two identical experiences against each other with no real treatment, purely to sanity check whether your randomization and data pipeline are working. Use use A/A tests when you’re standing up a new experimentation platform or a new metric pipeline.
The biggest mistake with these that I’ve seen across my experience is the experimenter trying to prove/disprove that the randomization algorithm might be biased. That’s the wrong question and mindset for using A/A tests. This question will only lead to distrust in the platform when there is absolutely no reason for it, but it keeps compounding with every additional A/A test that “fails.” The real question that needs to be answered is “How does the selected metric behave under the randomization function?” This question leads you to solve for the metric, which is typically done through metric engineering, i.e., studying the distribution and applying different variance reduction techniques.
Another mistake many people make is treating a single AA test as conclusive proof. In a true A/A test, the minimum detectable effect (MDE) is essentially zero, so you need an enormous sample to distinguish “no difference” from “not enough data yet.” One A/A test is a quick sanity check, but it is not proof, so tread with caution. Run eight or ten A/A variants in parallel with multiple comparisons correction instead. If the same metric flags as problematic across multiple variants, you probably have a real issue.

Validating an experimentation platform requires more than a handful of A/A tests. Repeated live or simulated A/A tests can help assess whether p-values follow their expected null distribution, using visual diagnostics and an appropriate goodness-of-fit test. These checks can detect problems with statistical calibration, but they do not rule out every form of bias or establish that enrolled users represent the target population.
In one case I observed, the platform’s enrollment algorithm favored frequent visitors, making the sample unrepresentative of the overall user population. This could go undetected by A/A tests if both variants drew from the same selected population. Even if observations within each variant were identically distributed, they would reflect a population that overrepresents frequent visitors. The identically distributed assumption alone therefore does not guarantee that results generalize to all users; enrollment representativeness must be checked separately by comparing who entered the experiment with everyone who was eligible to enter, as well as who did not enter.
Elasticity and Response Surface Methodology
Sometimes the right question isn’t “Should we do this?” but “How much should we do this?” You have a knob to turn in your business or product or algo—price, ranking weight, cache frequency, LLM scan depth—and you want to know where the sweet spot is.

An elasticity test sets up multiple arms at different levels of that knob instead of just on and off. You get a response curve that shows marginal return per unit of improvement, and where that return flattens out. Five to eight points on the curve gives you enough resolution to see the shape.

When you have multiple knobs to turn at the same time, Response Surface Methodology lets you test them in combination. Instead of optimizing each lever separately with elasticity alone (left), you set up arms that represent different combinations of values, fit a curve to the results, and find the peak (right). This takes more traffic and more complexity, but you see interactions between levers instead of assuming they’re independent.
These two methods, even though decades old, will be foundational for the next generation of experiments that are going to be driven by the rapid advancements in AI.
Sequential Probability Ratio Test (SPRT)
A standard frequentist A/B test commits to a sample size upfront. You collect that much data, then you look once. SPRT does the opposite: you decide in advance what evidence would convince you to stop, then you check continuously as data arrives.

The moment the evidence for “this works” or “this doesn’t work” crosses the threshold you set, you can stop. This is useful for safety-relevant changes where you can’t afford to wait three weeks to know if something is hurting people or your business. It is also useful when the effect is large enough that a fixed sample size would just waste time.
The key requirement is that you lock in your decision rule before you start for every metric you’re watching. If you decide after you see the data, it may not be the wrong thing to do once or twice, but getting into the habit of deciding to switch after looking at the data will bite your business outcomes in the long run.
Multi-armed bandits and contextual bandits
These are less an experiment design and more an optimization tool. Say you have five ad creatives. A standard A/B test sets up equal variants for the entire run, which means you’re paying full price the whole time to display creatives you already know are losing money.

A multi-armed bandit learns which creative is the best, then gradually shifts traffic from other variants toward it. You give up some precision in the final answer in exchange for far less regret, i.e., fewer people see a losing variant. But outcomes need to happen fast enough to inform those reallocations, and the performance landscape has to be relatively stable.

A contextual bandit goes further. Instead of learning which variant is globally best, it learns which variant is best for which type of user. This is how personalization engines work. You’re not converging on one winner for everyone. You’re matching variants to user context in real time. Contextual bandits live much longer than their simpler MAB cousins.
The designs and when to use them
The table below summarizes the experiments covered in this post.
# | Method | Use it when | Stats method |
|---|---|---|---|
1 | Standard A/B/n test | Testing acquisition surfaces or existing-user product changes | Two-sample frequentist or Bayesian with CUPED variance reduction |
2 | Standing up a new platform or a new metric pipeline, sanity checking homogeneity of randomization | Two-sample frequentist with multiple comparisons correction | |
3 | Not trying to improve the metric, just proving it didn’t become materially worse | One-sided hypothesis test against a prespecified non-inferiority margin | |
4 | Assigned at the account or org level and measured at the user level, great for B2B small samples | Two-sample frequentist with delta method for clustered, nested variance | |
5 | Program-level or quarterly “is this all paying off” reporting | Two-sample frequentist evaluating a longitudinal control group | |
6 | Market-level or geo campaigns where you can’t randomize individuals | Synthetic control with weighted donor blending | |
7 | Marketplaces, logistics, anywhere with network effects where one user’s treatment leaks into another’s | Time-block randomization with weighted least squares regression | |
8 | Prioritization calls: how much to invest, not whether to invest | Multi-arm dose-response curve | |
9 | Response Surface Methodology | Need to identify which combinations of multiple simultaneous changes perform best | Two-sample frequentist with multiple comparisons correction |
10 | Safety-relevant changes where waiting has a real cost | Sequential likelihood-ratio test | |
11 | Several live options where showing people a losing variant has a time-based cost | Thompson sampling (Bayesian) | |
12 | Several live options that match the variant to the user’s context, like personalization | LinUCB with logistic regression |
Start with the right question
The best experiment design is the one that answers the precise question you’re actually asking, just like Odysseus did. That sounds obvious after reading this post, but for many unsuspecting experimenters, it’s not. Most teams are given a tool, and then try to make it answer every question. If the answers don’t make sense, they assume there’s a measurement problem. But the real problem is usually that they asked the wrong question or violated an assumption without realizing it.
Like a great researcher, always start with the question. Then pick the design. The statistics follow from that, not the other way around.
End with the right tool
These advanced measurement methods are implemented at scale by the world’s largest tech companies, like Google, Netflix, Meta, Microsoft, DoorDash, and Uber. Most companies do not have the resources to build these capabilities in-house, so they turn to experiment platforms.
To democratize the same level of sophistication as the tech giants, advanced platforms like Statsig have many of these methods out of the box. Simple experimentation platforms have one or maybe two methods baked in, which could ultimately violate assumptions and lead to incorrect experiment reads.
If you’re evaluating a platform with advanced capabilities vs. running simple A/B tests, ask yourself whether any of your research questions may violate assumptions or would need a different method, today or as you grow.